












An application does not fail quietly. A dropped call, a frozen checkout screen, or a payment that never confirms is the moment a business's technology becomes visible to the person it's supposed to stay invisible to: the customer.
Application performance management (APM) is the discipline built to catch that moment before it happens. It monitors the applications behind unified communications, contact centers, and payment systems, collects the performance data that shows when something is drifting outside acceptable limits, and gives teams the means to act before customers notice.
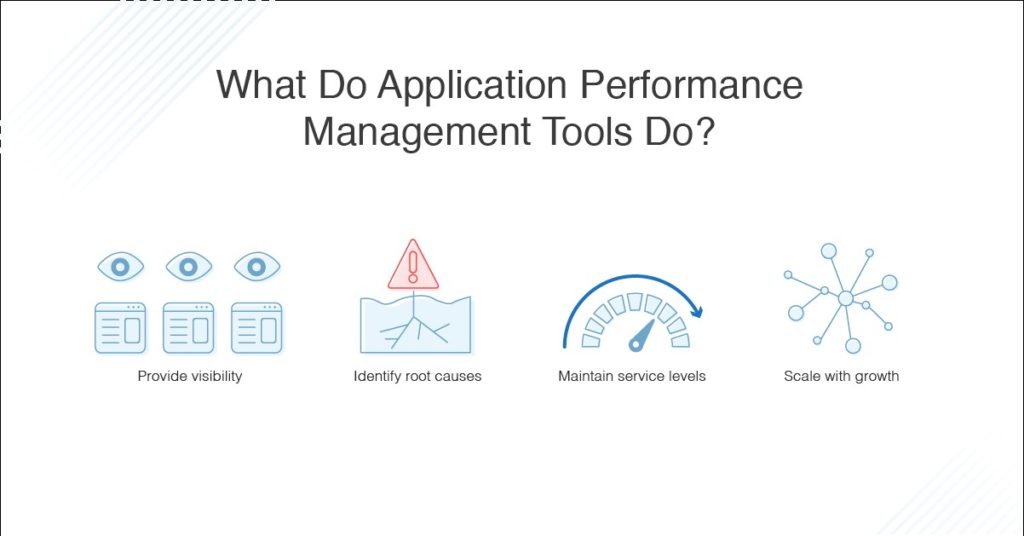
Image source: DNS Stuff
Why application performance management matters
APM turns application performance from a guess into a measurement.
Digital teams can't fix what they can't see. In a hybrid working world built on mobile applications and cloud-delivered communication platforms, APM gives teams the visibility to catch irregularities before they become outages. Without it, the problems don't disappear — they just surface later, and closer to the customer.
APM protects an organization's entire IT infrastructure by:
- Real-time data collection:
Gathering performance data continuously and analyzing it to surface problems as they develop, not after the fact. - Bottleneck prevention:
Measuring and monitoring application performance to catch degradation before it becomes a bottleneck. - End user experience monitoring:
Tracking user-defined transactions to see performance from the perspective of the person actually using the application. - Root cause analysis:
Pinpointing the real source of a problem, not just the symptom. - Actionable insight:
Turning raw performance data into decisions that improve the user experience.
How APM differs from observability
Monitoring tells you something is wrong. Observability tells you why.
Application performance monitoring and observability both work to identify the cause of a problem, but they answer different questions. The distinction matters because it decides how fast a team can move from "something broke" to "here's what to do about it."
The table below shows where each approach is strongest.
| Monitoring | Observability |
| Alerts you when a predefined threshold is breached | Lets you ask new questions about a system without shipping new code |
| Confirms whether something is wrong | Explains what's happening, why, and what to do next |
| Strongest for known failure modes and long-term trend analysis | Strongest for complex, distributed systems with unpredictable failure modes |
Neither replaces the other. Monitoring remains essential for known thresholds and long-term trends; observability becomes essential once systems are too complex and distributed for a predefined alert to catch everything that can go wrong. Read more in our guide to what observability actually means.

Image source: Chaos Genius
What application performance monitoring covers
A modern application isn't one thing — it's dozens of interconnected pieces, running everywhere at once.
A single customer transaction can touch dozens of interconnected services, hosted across multiple cloud providers, and built from millions of lines of code. APM gives teams visibility into that entire stack: application frameworks, APIs, memory usage, the operating system, real user sessions, databases, web application servers, and middleware. Infrastructure monitoring adds a layer underneath — CPU utilization, disk space, and network performance. Without that combined view, most organizations couldn't maintain the service level agreements their customers and regulators expect.
The technical case for APM
APM benefits IT operations, DBAs, DevOps engineers, site reliability engineers, and application developers directly. Tracking each component of the IT infrastructure — sometimes called an application component deep dive — delivers:
- Application stability and uptime:
Fewer surprises in production, and faster recovery when something does go wrong. - Fewer performance-related incidents:
Catching degradation before it becomes an incident, not after. - Faster response and resolution:
Less time spent finding the problem, more time spent fixing it. - Clear visibility into application health:
A real picture of how applications are performing, not an assumption. - Better infrastructure utilization:
Resourcing based on actual usage patterns instead of guesswork.
Load testing and stress testing using APM data can surface bottlenecks in application components and APIs before they show up in production.

Image source: Hostpapa
The business impact of application performance monitoring
Every technical fix APM makes possible shows up somewhere on the P&L.
Every organization is looking for an edge in performance, and a properly used APM solution delivers one: fewer outages, faster recovery, and a better customer experience translate directly into revenue and retention.
Reduced mean time to recovery (MTTR)
Outages and performance incidents are going to happen. MTTR measures how much risk each new release or infrastructure change introduces — and it's the metric APM improves most directly. Instead of responding reactively once something breaks, APM makes it possible to catch degradation through analytics and performance data before it becomes an incident.
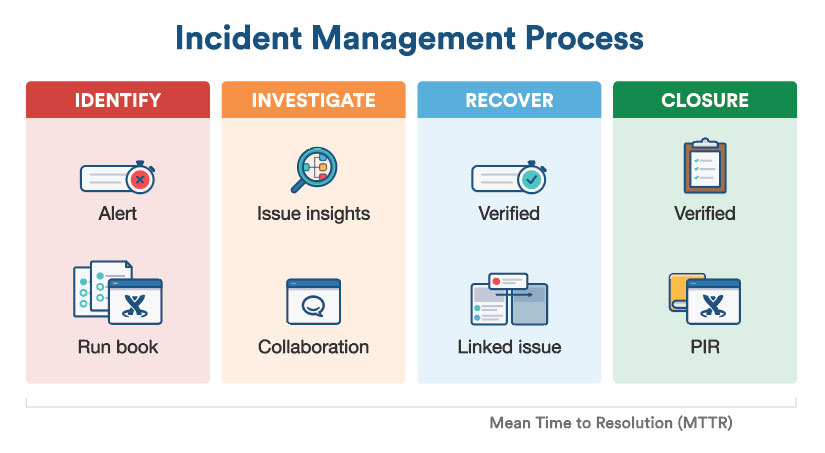
Image source: Atlassian
Diagnosing software anomalies before they become outages
Not every performance problem causes an outage. A software bug can degrade the user experience for weeks without ever triggering an alert. APM identifies the root cause of those quieter problems too, which stabilizes the application, supports product growth, and reduces customer churn.
User-defined transaction profiling
This tracks a single user's activity within an application as one connected transaction — from login through every back-end process tied to that session — rather than as a collection of disconnected events.
End user experience: the metric that matters most
Every technical and business benefit of APM eventually rolls up into one outcome: customer satisfaction. Whether the goal is cutting unnecessary spend, reducing bottlenecks, improving stability, or refining a specific application component, the result of deploying APM well is a better experience for the person actually using the application. For more on connecting that experience to revenue, read Transaction Analytics: The Key to Improving Customer Experience.
Why payments and financial services depend on APM
For a bank or payments provider, a slow transaction isn't an inconvenience — it's lost revenue.
Financial services carries its own version of the APM problem, and a sharper one. Most organizations in this space depend directly on online transactions for revenue, so zero-fail application performance isn't a nice-to-have — it's the business. Transaction speed and system stability drive customer retention as much as any product feature does.
A transaction-based approach to APM puts that dependency front and center:
- Monitor every real transaction, end to end:
Track each transaction through its full lifecycle from the customer's perspective, to see exactly where it slows down or fails. - Use that data to fix the slowest paths first:
Identify the highest-volume transactions with the slowest response times, and prioritize those for the biggest gain in customer experience.
APM tools vs. APM platforms
Most organizations don't start with a platform — they end up needing one.
Most organizations start with individual APM tools, each addressing one specific aspect of performance. Over time, that compounds: multiple tools that don't integrate with each other, and no way to see the full picture when something goes wrong. That siloed setup makes root cause analysis slower, not faster.
An APM platform consolidates that into a single view, using AI, machine learning, and automation to analyze the application environment in context — across the full stack and the hybrid multi-cloud network underneath it. That gives teams continuous visibility into system degradation, resource usage, and performance anomalies, instead of switching between tools to piece it together. See how the two approaches compare in our 2026 observability tools comparison.
Why cloud-native applications make APM harder
Breaking an application into fifty microservices makes it flexible. It also makes it hard to see inside.
Cloud-native applications are built from loosely coupled microservices, usually packaged and run in containers. That structure makes them flexible and scalable — and hard for traditional APM and observability tools to see inside. Dividing an application into more, smaller pieces increases the number of places something can go wrong, without a matching increase in visibility.

Image source: Ambassador
Observability and monitoring tools have to integrate directly into the cloud-native environments they support, with deployment and instrumentation fully automated — not bolted on afterward.

Image source: IBM
That complexity multiplies with the number of monitoring layers involved: container monitoring, infrastructure monitoring, API monitoring, synthetic monitoring, network monitoring, database monitoring, log monitoring, and end-user monitoring. Many organizations run a separate tool for each, especially where legacy applications are still in the mix — which is exactly the tool sprawl an APM platform is built to replace.
How IR can help
Complexity doesn't go away. It just needs a single place to watch it from.
Digitalization means a growing set of technologies running constantly, whether that's unified communications and collaboration, payments, or infrastructure. IR's observability and monitoring solutions are built to simplify that complexity for the organizations that can least afford downtime — hundreds of the world's largest enterprises rely on IR to keep payment hubs, communications ecosystems, and contact centers running as they should.
Payments monitoring with IR Transact
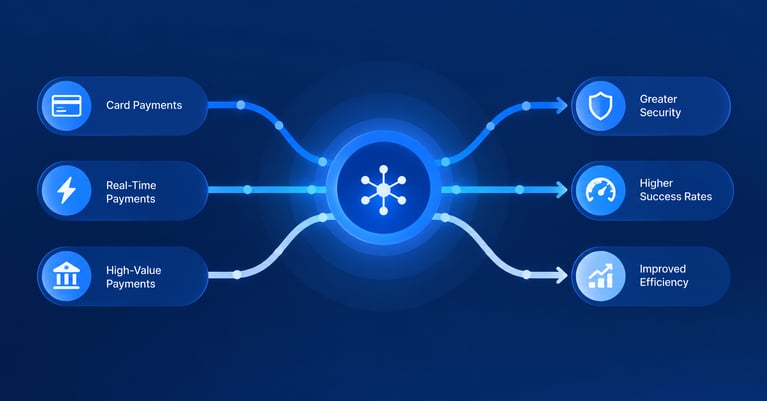
IR Transact gives payments teams a single view across high-value, card, and real-time payment environments — on-premises, cloud, or hybrid — so failures surface before they hit revenue or customer trust.


- End-to-end transaction visibility:
See every transaction across gateways, providers, and channels in one place, instead of piecing it together across siloed tools. - Faster root cause analysis:
Trace a failed or delayed transaction back to its source before it repeats. - Multi-vendor support:
Monitor and manage vendor solutions across on-premises and cloud deployment models from a single platform.
Unified communications and collaboration with IR Collaborate
Hybrid working has raised the bar for uptime and problem resolution across UC and collaboration platforms. IR Collaborate connects Microsoft Teams, Cisco, Avaya, Oracle, and more into a single view, without locking teams into one vendor.

- Enterprise UC visibility:
End-to-end visibility across the multi-vendor UC ecosystem, so issues get identified and resolved faster. - Contact center reliability:
Automated alerts that flag problems based on real-time trends, reducing helpdesk calls and troubleshooting time. - Experience testing:
Outside-in testing of voice, web, and video to confirm customer-facing quality before customers notice a problem.
Whether it's a dropped call or a failed transaction, the application is where a digital strategy either holds up under pressure or doesn't. APM is what tells a team the difference before the customer has to.
Request a demo